Growth Systems
Why Growth Experiments Fail to Produce Learning and How to Fix It
A practical framework connects the decision, assumption, test, evidence and next action so growth experiments produce reusable business learning.
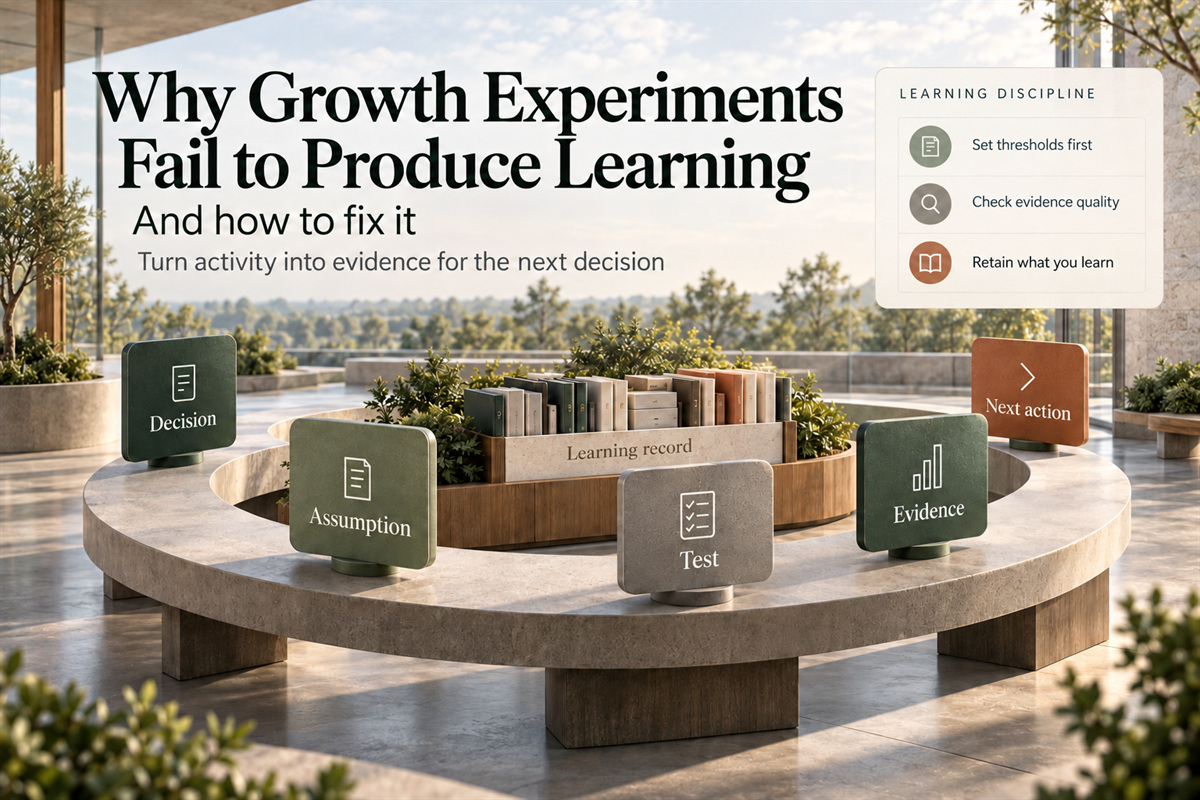
The Pilot Finished. What Did the Business Learn?
Imagine a leadership team reviewing a completed partnership pilot. The presentation shows customer meetings, positive feedback, and several new accounts. Everyone agrees the team worked hard.
Then the CEO asks, “Should we expand?”
The room goes quiet. Nobody established what expansion would require. Delivery costs were not tracked consistently. The strongest customers received exceptional support. The original assumptions are buried in a proposal.
The pilot produced activity. It did not produce a dependable basis for the next decision.
A business experimentation framework should connect five things: the decision, the assumption, the test, the evidence, and the next action. Its purpose is not to make every experiment succeed. It helps the business learn deliberately and retain what it learns. This is applying the scientific method to business.
Why Growth Experiments Fail to Produce Useful Learning
Start by looking for four breakdowns.
The experiment has an activity goal, not a learning question.
“Launch a pilot” describes work. It does not identify what the business needs to discover. Without that distinction, a team can finish everything on its project plan while leaving the investment decision unresolved.
Success is defined after the results arrive.
Suppose adoption disappoints, but satisfaction looks encouraging. Recasting the initiative as a satisfaction test changes the question after seeing the answer.
Microsoft’s experimentation research highlights a related statistical risk: examining many metrics increases the chance of finding apparently significant results that reflect noise rather than a real effect. Selecting favorable metrics afterward is not a sound basis for a decision.
The test cannot separate the explanations.
Price, onboarding, customer selection, and sales support might all change together. The results may describe how that package performed, but they do not establish which component mattered.
Isolating key variables is key to maximizing the learning value of growth experiments. NIST’s experimental-design guidance emphasizes planning factors and outcomes, including potential interactions. Planning to separate the explanations is a key part of good test design. Knowing which components matter to a result enables the team to construct stronger hypotheses for the next experiment.
The conclusion stays with the project team.
A presentation is not the endpoint. Close the initiative only when its findings, limitations, and resulting decision are accessible to whoever will make the next related commitment.
Most importantly, do not treat every disappointing result as the same kind of failure. Evidence against an assumption, insufficient evidence, and an implementation breakdown call for different responses. “We learned a lot” should introduce an explanation that creates value for the whole organization, not be the explanation.

A Business Experimentation Framework That Starts With the Decision
Use the following sequence to organize learning across pilots, partnerships, market tests, and internal initiatives. It is a practical operating approach, not a requirement to turn every project into an A/B test.
1. Select Measures That Match the Decision
Begin with the business result that matters and the commitment it should inform. Are you deciding whether to expand a channel, change a process, or fund another stage of development?
Distinguish Core Growth, Market and Product Adjacencies, and Disruptive Potential when choosing measures.
For a core initiative, prioritize measures such as contribution margin, retention, or delivery cost. For an adjacency, test whether customer demand and delivery capabilities transfer. For an early disruptive opportunity, prioritize evidence about adoption, customer trade-offs, and economic assumptions before demanding mature-business returns.
Keep financial projections separate from observed results.
2. Identify the Assumption Most Likely to Change the Commitment
Ask, “What must be true for this opportunity to deserve more resources?”
A partnership might depend on access to qualified buyers, repeatable delivery, or acceptable support costs. These are separate assumptions. Test the most consequential unresolved one, not simply the easiest.
Maintain strategic coherence, too. Before funding a test, explain how the potential opportunity supports the company’s chosen direction. Evaluating a growth opportunity before committing resources provides a broader assessment around this decision.
3. Write a Hypothesis Someone Else Can Assess
Use a consistent structure:
“We believe [specific change] will produce [observable outcome] for [defined group] within [appropriate period], because [underlying explanation].”
For a hypothetical onboarding test: “We believe a guided setup will increase activation among first-time small-business customers because it removes the configuration step where they currently stop.”
Define “activation,” the comparison, and the minimum worthwhile improvement separately. A hypothesis should make disagreement testable, not hide it behind words such as “better” or “successful.”
4. Choose a Method That Answers the Question
Use interviews to explore motivations and objections. Use prototypes to investigate how people interact with a proposed solution. Use pilots to examine behavior, delivery effort, and practical constraints.
Do not treat these methods as interchangeable. A positive interview does not establish a purchase rate. A before-and-after improvement without a credible comparison does not, by itself, establish that your intervention caused it.
For causal questions, use an appropriate controlled comparison when feasible, and seek methodological support when the stakes warrant it. NIST’s design-selection guidance makes the underlying principle clear: choose the design around the objective, factors, and acceptable risk of a wrong conclusion.
5. Agree on Thresholds, Boundaries, and Ownership
Before launch, document the primary outcome, safeguards, spending limit, review timing, and decision owner.
Set a minimum commercially worthwhile result and explain why it matters. Distinguish that business threshold from statistical evidence: clearing a target does not automatically establish a reliable effect.
Plan a sample and observation period appropriate to the question. Include enough time to observe the behavior that matters, whether that is repeat usage, a purchase, or completed delivery.
Record changes to the plan. Treat unexpected findings as exploratory unless the analysis appropriately accounts for their discovery.
6. Check Evidence Quality Before Interpreting Performance
Confirm that the initiative actually ran as intended. Were the intended participants reached? Were outcomes recorded consistently? Did unusual support, missing data, or changes in customer mix affect interpretation?
Research on trustworthy experimentation under telemetry loss shows that missing measurement data can bias results and lead to incorrect conclusions.
Then examine the size and uncertainty of the observed difference, not just whether a dashboard labels it significant. When evidence remains too weak to distinguish a worthwhile improvement from no improvement, report the uncertainty.
Don't turn an unresolved question into a confident yes or no.
Capture Findings in a Learning Record, Not Just a Presentation
Create one record before the test and update it afterward. Keep the original hypothesis and thresholds visible rather than overwriting them to match the outcome.
NIST’s practical experimentation checklist recommends retaining raw data, documenting events, and maintaining ownership throughout the experimental plan. For business initiatives, extend that discipline to the decision and its rationale.
Separate observation from interpretation. “Customers required repeated setup assistance” is an observation. “The onboarding model needs redesign” is an interpretation to assess against the evidence.
Preserve negative findings and unsuccessful attempts alongside positive outcomes. Add dates, versions, and links to related tests so a future team can reconstruct what changed.
Keep sensitive information appropriately restricted. A searchable learning system does not require making every customer record visible to everyone.
Turn Learning Into an Explicit Decision
At closeout, answer two questions separately: What does the evidence support? What should the business do?
The first answer might be that an assumption gained support, lost support, or remains unresolved. Record implementation problems separately.
The second answer could be to expand cautiously, revise the approach, run another test, stop, or defer until a named condition changes.
A promising finding does not automatically justify scaling. It may justify only the next limited commitment. Likewise, an inconclusive test does not automatically mean that more testing should be done.
Require a rationale for further work: Which remaining uncertainty matters, and how would resolving it change the decision?
Give the next action an owner and deadline. Review evidence quality and decision follow-through rather than rewarding teams simply for reporting a high experiment success rate.
Apply the Framework Across Different Growth Initiatives
Consider a hypothetical software company testing a distribution partnership. The numbers below are illustrative, not industry benchmarks.
Before launch, leadership sets a commercial gate for considering a larger trial: at least five paying customers from the defined prospect group, with average onboarding effort below ten staff hours per customer.
The pilot produces six customers. Average onboarding takes eighteen hours, and senior engineers handle repeated exceptions.
Calling the partnership successful would ignore delivery. Calling it a total failure would ignore the sales evidence.
A more useful conclusion is: some prospects bought under the tested conditions, but the delivery model missed the agreed effort limit. Without an appropriate comparison, the team should not claim the partnership caused incremental sales.
The next decision could be to test a narrower integration scope before expanding the partnership. Link that test to the original learning record, preserving the unresolved questions about repeatability and acquisition economics.
The same discipline applies elsewhere.
Product pilot: Investigate repeat usage after guided setup, not simply participation in a demonstration.
Market-entry test: Examine purchase commitments and buying-cycle constraints, not only responses to introductory outreach.
Internal initiative: Evaluate time saved alongside error rates and work shifted to other teams.
For the customer-facing work, pair this process with rapid customer learning techniques.
Finally, record where the evidence applies. Microsoft’s research on external validity explains why findings from one population or time period may not transfer to another. A result among selected pilot customers should not become a universal rule for every segment.
Start With a Lightweight Learning System
Begin with one active initiative, one learning-record template, and one shared location. Assign a record owner and add the closeout discussion to an existing leadership review.
Tag findings by assumption, customer segment, growth opportunity, and operating process. Before approving another experiment, require a search for relevant prior learning.
Track whether records lead to decisions and whether resulting actions are completed. Use those measures to find gaps, not to manufacture another volume target.
Use this as a starting point for moving from firefighting to a Growth System: make evidence reusable without creating a separate reporting bureaucracy.
Make Learning Part of How the Business Grows
The goal is not a larger collection of experiments. It is a better-informed sequence of commitments.
A useful business experimentation framework keeps the original question visible, separates observations from explanations, and makes uncertainty explicit. It also gives future teams enough context to reuse a finding or recognize when it needs another test.
A learning-oriented approach needs clear priorities, resource allocation, and continuous improvement. The implication here is practical: connect what teams discover to how leaders allocate attention, talent, and capital.
That fits Leverage Co.'s Growth Systems approach, which brings together governance, customer learning, iteration, and project prioritization.
Start with a diagnostic question:
“Which important business decision changed because of your last experiment, and could another team find the evidence behind it?”
When the answer is unclear, begin by repairing that connection. Choose the decision, expose the assumption, define the evidence, and record the next action.
